Kevin-thu
StoryMem
Give it a shot list, get a minute-long multi-shot video
- Wan 2.2 T2V-A14B
- Wan 2.2 I2V-A14B
- StoryMem Wan2.2 M2V-A14B
- +1

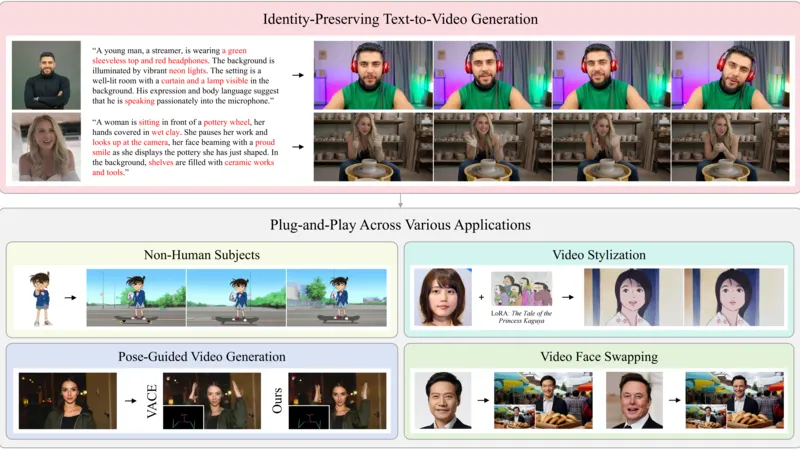
Stand-In adds a consistent face to Wan video generation from one photo. It trains only about 1% extra parameters, so the base model stays frozen. You get scripts for text-to-video, LoRA styles, face swapping and VACE pose control. Training code and dataset aren't out yet, and face swapping is experimental.
Best for: Technical artists who need one face to stay consistent across Wan-generated shots.
Rewritten from the README. Check the repo for the latest steps.
conda activate Stand-Ingit clone https://github.com/WeChatCV/Stand-In.gitconda create -n Stand-In python=3.11 -ypip install -r requirements.txtcheckpoints: python download_models.py (add --wan_version 2.2 for Wan2.2, --vace for VACE)python infer.py --prompt "..." --ip_image "test/input/lecun.jpg" --output "test/output/lecun.mp4"python infer_with_lora.py with --lora_path and --lora_scalepython infer_face_swap.py with --denoising_strengthOther model tooling projects people compare with Stand-In.
Kevin-thu
Give it a shot list, get a minute-long multi-shot video
KlingAIResearch
Chains multi-shot video frames on the fly for interactive stories
aigc-apps
Python toolkit that makes AI video and trains your own models
deepbeepmeep
Desktop app that runs open video, image and audio models on your own PC
Do you maintain Stand-In? Add this badge to your README so English speakers can find our write-up.
[](https://openmicrodrama.com/projects/wechatcv-stand-in)The badge links to this page. Want your description changed? Email support@openmicrodrama.com.
Reviewed Oct 1, 2026. Built on Wan2.1 and DiffSynth-Studio. The third-party ComfyUI node differs from the official version. We write these descriptions ourselves. The repo's own docs are the final word.